Why Your Product's Data Architecture Is Blocking AI Integration (And How to Fix It)
Most founders want to add AI to their products but can't. The real problem isn't the AI—it's a fragmented data layer. Here's how to architect it properly.
Aamir Sohail, Co-Founder, XenonDev
, 8 min read
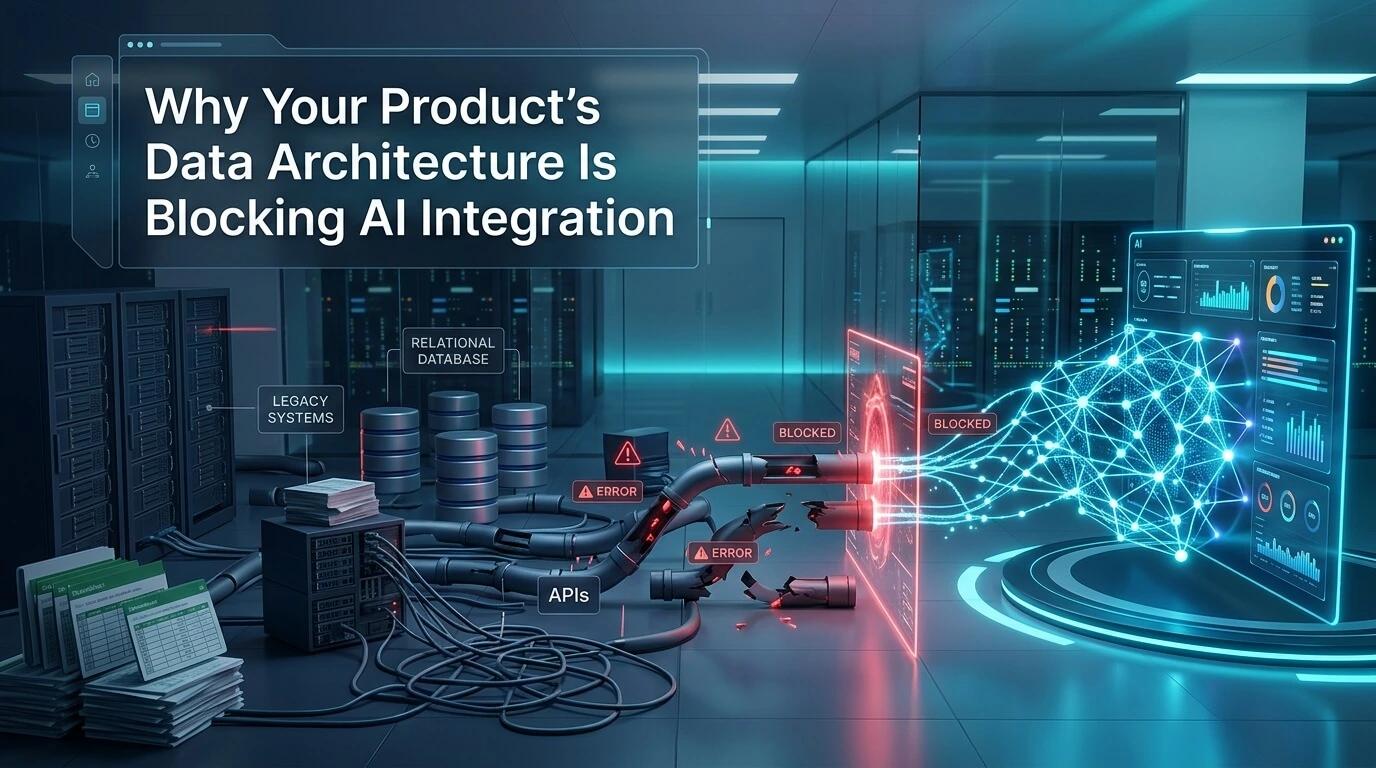
You want to add AI to your product. Your users would love it. Your roadmap has it flagged for Q3. But when your engineering team starts digging into what it would take to integrate an LLM, automate workflows, or build predictive features, everything grinds to a halt. The culprit? Your data isn't structured for AI. It's structured for CRUD operations—create, read, update, delete. Those are completely different things.
We've seen this pattern dozens of times with founders and operators we work with at XenonDev. The product works beautifully for its core use case, but the underlying data architecture wasn't designed with AI or automation in mind. Data lives in silos. Context is scattered across multiple tables with weak relationships. Audit trails don't exist. Historical data is missing. What takes a human 10 minutes to understand and act on would take an AI system hours to reconstruct—if it could do it at all.
The good news is that this is fixable. But it requires thinking about your data layer differently—not just as a place to store operational state, but as a foundation for intelligent systems to learn, reason, and act. Let's walk through the core problems we see, and exactly how to restructure your data architecture for AI integration before it becomes a blocker.
Problem 1: Your Data Lacks Rich Context
Most traditional SaaS databases store minimal information—just enough to render the UI and process transactions. A user record has name, email, company ID. An order has items, total, timestamp. But an AI system needs context. What was the user's decision-making process? What were they looking at before they acted? What patterns preceded this action?
Here's a concrete example: a product analytics platform wants to add an AI feature that recommends which metrics a user should monitor next. The AI needs to understand what they've already looked at, how long they spent on each view, what questions they asked in chat, which dashboards they created, and what segments they filtered. But if your database only stores 'user viewed dashboard X at timestamp Y,' the AI is flying blind. It can't understand intent, preference, or domain expertise.
The fix starts with thinking about data enrichment at the schema level. Every user action—not just transactions—should be captured with rich metadata. When someone creates a document, store not just the final version, but the intent signals: search queries that led them there, collaborators involved, templates they referenced, edits they made. When someone makes a decision, log the context: what data they looked at, how long, alternatives they considered.
How to Implement: Event-Driven Data Capture
Move from transactional logging to event-based logging. Instead of only recording the final state ('user purchased product'), record the entire journey as discrete, immutable events: 'user viewed product page', 'user added item to cart', 'user applied discount code', 'user completed purchase'. Each event should include rich context: user properties at that time, page state, duration, device info, and any derived signals. Store these in an event store or append-only log, separate from your transactional database. This gives AI systems a complete picture of behavior and decision-making, not just outcomes.
Problem 2: No Historical Data or Audit Trail
Many products update records in place. A user's status changes from 'prospect' to 'customer' and the old value is overwritten. A budget is adjusted and the previous number is lost. An attribute is corrected and the history is gone. From a transactional standpoint, this is fine—the system reflects current state. From an AI standpoint, it's catastrophic. Machine learning models learn from patterns in historical data. If there's no history, there's nothing to learn from.
Consider a sales platform that wants to predict deal closure likelihood. The model needs to understand how deal stage progresses, how long deals typically spend in each stage, what causes deals to stall or accelerate, and what external signals correlate with closure. But if you only store the current deal stage and amount, and overwrite those fields when they change, the model can't learn anything. It has no signal. It needs the timeline: when did the deal move to this stage, from what previous stage, who made the change, what triggered it?
The solution is temporal data modeling. Design your database so that changes are never destructive. When a record changes, you don't update it—you create a new version with an effective timestamp. The old version is still there, but marked as inactive. This gives you a complete audit trail and provides AI systems with the temporal signals they need to learn causality, predict sequences, and understand change dynamics.
How to Implement: Soft Deletes and Versioning
Add two timestamps to every record: 'valid_from' and 'valid_to'. When a record is created, valid_from is set to now and valid_to is NULL (meaning current). When that record is updated, you don't modify it—instead, you set its valid_to to now and insert a new row with the new values and a new valid_from timestamp. For deletions, set valid_to instead of removing the row. This approach—often called Slowly Changing Dimensions in data warehousing—gives you a complete history without breaking your transactional logic.
The operational queries still work (just add WHERE valid_to IS NULL to get current records), but now you have a historical ledger. AI systems can analyze entire timelines, understand state transitions, and learn from patterns across time. For compliance and governance, you also get automatic audit trails.
Problem 3: Data Lives in Silos Without Clear Relationships
It's common for growing products to have data scattered across multiple databases, services, and data stores. User data in one database, transactional data in another, behavioral data in an analytics warehouse, support tickets in a third system, billing in a fourth. Each system was built for a specific purpose, and connecting them is hard. There's no clear way for AI systems to traverse across contexts and understand the full picture of a user, account, or entity.
Imagine building an AI chatbot for customer support that needs to answer questions about account health, recent purchases, support history, and billing issues. If support tickets live in one system, purchase history in another, account data in a third, and billing in a fourth, the chatbot can't give coherent answers. It would need separate queries to five different sources, and there's no guarantee those sources agree on customer identity or account status.
The fix is a unified data model with clear, strong relationships. This doesn't mean cramming everything into one database. It means establishing a canonical schema with clearly defined entities and relationships, then mapping all your source systems to that schema. Create explicit foreign keys and relationship mappings. When data is fragmented, use identifiers to link them (a customer ID that's consistent across systems, for example). Build a data integration layer that keeps these mappings fresh.
How to Implement: Create a Data Ontology
Start by documenting your core entities: what is a user, an account, a transaction, a relationship? Define clear rules for how they relate to each other. A user belongs to an account. An account has multiple transactions. A transaction involves a product. A user has support tickets. Build this as a simple ERD (entity relationship diagram) that spans all your systems, not just one database.
Then build a lightweight data integration layer—this could be a service, an ETL pipeline, or even a well-documented SQL view layer—that maps each source system to this canonical schema. Use consistent identifiers. If a customer has an ID in your main database, the same ID should be used in your analytics warehouse, billing system, and support system. When AI systems query for context, they now have a single semantic model to work with, even if the underlying data lives in multiple places.
Problem 4: Missing Derived Signals and Pre-Computed Features
Raw data isn't useful to AI systems without preprocessing. A list of transactions doesn't tell you about spending patterns. A list of logins doesn't tell you about engagement trends. A list of page views doesn't tell you about feature adoption. AI systems need features: derived, computed attributes that capture meaningful signals from raw data. If you expect the AI system to compute these on the fly, it will be slow, expensive, and brittle.
For example, an AI system predicting churn needs features like 'days since last login', 'average weekly usage', 'feature adoption score', 'support ticket sentiment trend', and 'contract renewal date approaching'. Computing these fresh every time you want to make a prediction is inefficient. Instead, you should have a feature store—a layer that pre-computes these signals and keeps them updated as new data arrives.
The key is to identify which signals are most valuable for your AI use cases, then build them into your data architecture as computed columns, views, or a proper feature store. This is a line between raw data (the source of truth) and AI-ready data (optimized for inference and learning). Once you have it, AI systems can move fast and reliably.
How to Implement: Build a Feature Layer
Start simple: create a features table where each row is a customer (or entity of interest) and each column is a computed signal. Examples: 'last_login_days_ago', 'features_used_count', 'avg_session_duration', 'support_tickets_last_30d', 'nps_score', 'contract_value'. You can compute these in batches daily or weekly using SQL queries or lightweight scripts.
As you scale, you can graduate to a proper feature store tool like Tecton or Feast, but a well-organized table in your data warehouse works fine to start. The key is consistency: define each feature clearly (how is it calculated, what does it mean, when is it updated), version them, and treat this layer as part of your product's data contract. AI systems should depend on these precomputed features, not raw data.
Building an AI-Ready Data Architecture: The Action Plan
You don't need to rebuild your entire database architecture overnight. But you do need a plan. Start by auditing your current state: do you capture rich context around user actions? Do you have historical data with audit trails? Are your entities and relationships clearly defined? Do you have precomputed features? Identify the biggest gaps first.
Then prioritize based on your AI roadmap. If your first AI project is a recommendation engine, focus on capturing behavior data and building the features it needs. If it's a chatbot, focus on unified entity relationships and historical context. If it's predictive analytics, focus on temporal data and historical signals. Each AI use case has different requirements, and you should structure your data accordingly.
At XenonDev, we've seen founders go from 'we can't integrate AI' to 'we shipped an AI feature' in weeks once the data layer was fixed. The engineering effort moves from 'try to reconstruct context from fragmented data' to 'build the intelligence layer on top of clean data'. It's a fundamental difference. If you're planning AI features but your data architecture isn't ready, this is the place to start.